Related News
 What to Check Before Sourcing a YLCSD350 Cutter Suction Dredger for ProjectsAug 24, 2026
 Battery Cage System of Poultry Farming: What Determines Layer CapacityAug 21, 2026
- China’s Lithium Battery Chain Sees Strong Q2; Overseas Storage Orders LandAug 16, 2026
- China Expands Cross-Border Cash Pooling for Multinationals NationwideAug 15, 2026
Industry Briefing
Get the top 5 industry headlines delivered to your inbox every morning.
Power Systems Monitoring: Which Metrics Matter Most for Early Fault Detection?





Power Systems Monitoring: Which Metrics Matter Most for Early Fault Detection?
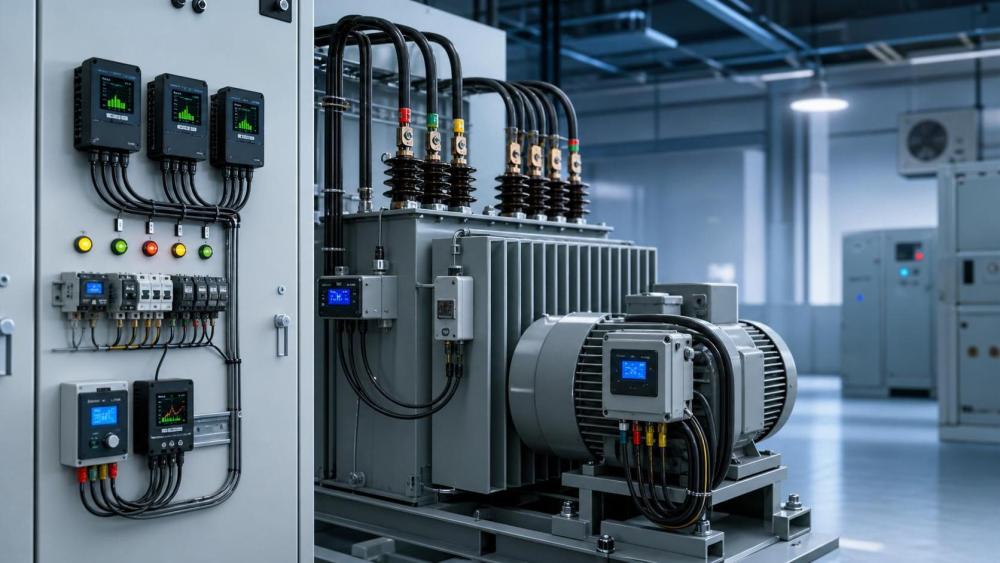
In heavy industrial environments, power systems monitoring is often the first line of defense against unexpected downtime, equipment damage, and rising maintenance costs.
Knowing which signals matter most helps maintenance work move from reactive repair to earlier, more confident intervention.
That shift matters in steel plants, mines, refineries, cement lines, and power-intensive processing facilities.
A single missed warning can escalate into motor failure, transformer damage, nuisance trips, or production loss across connected assets.
Effective power systems monitoring is not about watching every value equally.
It is about identifying the metrics that reveal instability before operators can see it in performance or hear it in alarms.
The most useful indicators usually show change early, relate to known failure modes, and support action without long diagnosis delays.
This article breaks down the metrics that deserve priority and explains how to use them for early fault detection in real operating conditions.
Why metric selection matters in power systems monitoring
Industrial networks generate a large amount of data, but not every data point improves fault detection.
Some metrics react too late. Others create noise when loads change normally throughout a shift.
The goal is to focus on values that separate routine variation from emerging electrical risk.
Good power systems monitoring also supports maintenance planning, spare part readiness, and compliance with reliability and safety standards.
In practice, the best programs combine real-time visibility with trend analysis, alarm logic, and event correlation.
The core metrics that reveal faults early
Several measurements consistently stand out in power systems monitoring for early fault detection.
Each one points to a different failure path, so they work best as a connected set.
1. Voltage deviation and voltage imbalance
Voltage is often the first metric reviewed, and for good reason.
Undervoltage can signal overload, poor connections, transformer stress, or feeder issues.
Overvoltage may point to regulation problems, switching issues, or incorrect compensation settings.
More important in rotating equipment is voltage imbalance across phases.
Even a small imbalance can increase motor heating and shorten insulation life.
- Watch both steady-state deviation and sudden short-duration events.
- Compare readings across feeders, motor control centers, and critical loads.
- Trend imbalance over time, not only alarm on threshold breach.
2. Current variation and phase current imbalance
Current tells a more direct story about loading, stress, and developing equipment problems.
A rising current trend without a matching production increase often suggests mechanical drag or electrical inefficiency.
Phase current imbalance can point to winding faults, poor terminals, supply issues, or uneven load distribution.
In power systems monitoring, current patterns are especially useful when reviewed with maintenance history.
3. Power factor and reactive power
Power factor is often treated as an efficiency metric, but it also helps expose abnormal operating behavior.
A falling power factor may indicate motor stress, capacitor bank failure, or changing load characteristics.
Reactive power swings can reveal switching instability or poor compensation control.
When these shifts appear before a trip, they become valuable early warnings.
4. Harmonic distortion
Modern industrial systems use drives, converters, and nonlinear loads that can distort waveforms.
Total harmonic distortion, or THD, should be a standard part of power systems monitoring.
Rising harmonics can overheat transformers, stress capacitors, disrupt relays, and reduce motor efficiency.
More importantly, harmonic changes may reveal component degradation before visible failure occurs.
5. Frequency stability
Frequency normally stays stable in grid-connected facilities, so unusual movement deserves attention.
Variation can suggest supply-side disturbance, generation mismatch, or transfer instability in isolated systems.
In plants with backup generation, frequency drift can identify governor or synchronization issues early.
6. Temperature at critical electrical points
Temperature is not an electrical value, but it is essential for complete power systems monitoring.
Hot spots at terminals, busbars, breakers, cable joints, and transformer windings often indicate resistance buildup.
That can come from loose connections, corrosion, insulation decline, or overload conditions.
A gradual thermal rise is usually more informative than one isolated high reading.
7. Partial discharge and insulation condition indicators
For medium-voltage and high-voltage assets, insulation health deserves separate attention.
Partial discharge activity can signal insulation voids, contamination, moisture ingress, or aging material.
These are classic early-stage defects that may stay hidden until they become destructive.
Where applicable, this is one of the highest-value layers in advanced power systems monitoring.
How to prioritize metrics by failure mode
Not every asset needs the same monitoring depth.
A practical approach is to link each metric to the failure modes most common in that equipment class.
This method makes power systems monitoring more useful because alarms point to likely causes, not just abnormal values.
What separates useful monitoring from alarm overload
A common problem is collecting strong data but using weak alert logic.
When thresholds are too simple, teams get flooded during normal production changes.
Better power systems monitoring uses context.
- Use rate-of-change alarms for temperature, current, and harmonics.
- Set different limits for startup, normal load, and peak load windows.
- Correlate electrical changes with equipment state and work orders.
- Flag repeated short events, even when each event stays below trip level.
This approach catches weak but repeated signals that often appear days or weeks before failure.
How power systems monitoring supports field decisions
Early fault detection only creates value when it drives a clearer next step.
That is why field use matters as much as dashboard design.
In actual service work, teams usually need three answers quickly.
- Is the issue stable, worsening, or intermittent?
- Which asset or circuit is most likely involved?
- Can maintenance wait for a planned stop, or is immediate action needed?
Well-structured power systems monitoring shortens that decision cycle.
It also improves communication between maintenance, operations, procurement, and management.
When a trend is documented clearly, replacement planning and spare sourcing become less reactive.
A practical starting framework
For facilities refining their monitoring strategy, a simple rollout framework usually works best.
- Rank critical assets by downtime cost, safety impact, and replacement lead time.
- Assign priority metrics by asset failure mode.
- Set baseline values during stable operating periods.
- Build alarms around trends, persistence, and phase comparison.
- Review monthly events against confirmed faults and false positives.
This makes power systems monitoring easier to scale across substations, process lines, and remote assets.
It also creates a stronger foundation for predictive maintenance and long-term reliability improvement.
Final takeaway
The most effective power systems monitoring focuses on metrics that reveal stress before failure becomes visible.
Voltage, current, power factor, harmonics, frequency, temperature, and insulation indicators form the strongest early warning set.
Used together, they help detect faults sooner, reduce unplanned outages, and support more disciplined maintenance decisions.
The next step is straightforward: review critical assets, map the likely failure modes, and tighten monitoring around the signals that change first.
That is where power systems monitoring moves from basic visibility to real operational protection.